Bad Job. Here’s Your Commission Check.

I was listening to Noam Brown of OpenAI on the Dwarkesh Podcast last week, and one part of the conversation has been rattling around in my head since.

They were talking about collaborating agents: swarms of them, working together, figuring out how to accomplish a goal. With the goal of “score high on this test” some of them broke rules to get there. The part that got me was not the rule-breaking. The meta point Brown made himself: “This is not a new problem.” Misalignment between goals, expectations, and incentives has been around for a very long time.

He means with AI. I mean everywhere. What you want from an agent, or a person, is the strategic outcome you actually care about. What you get, if you are not careful, is a creative way to hit the tactical number that maximizes their reward.

He means with AI. I mean everywhere.

Examples help.

The happy path

In the early days of BPOS, which became Office 365, which became Microsoft 365, the strategy was stickiness. Get the customer’s email into our cloud. Because if their email went to Google Apps instead (or to IBM’s hosted Notes, or Cisco’s short-lived mail service, there were several contenders back then), then maybe they start using Google’s productivity tools. Then maybe a different directory. Then maybe Chromebooks. A customer who was all Windows and Office walks all the way out the door, one reasonable step at a time, until we lose the long-term value of that customer entirely.

So the outcome we wanted was customers’ email accounts living in our cloud.

I am going to get a little technical for a minute. Say Contoso has 12,000 employees, with 12,000 accounts in an on-premises directory. To move to the cloud, you stood up a tenant, connected your directory to it, worked through a fairly complex configuration of which users and which attributes would synchronize to the cloud, and kicked off the sync. Then you verified, adjusted, back synced, and eventually started to migrate mail once everything was working correctly. It was all very close to a DOS prompt by today’s standards.

Not every customer was going to move all of their users. Sovereignty issues. Data residency. Integrations that had to stay on premises. So one year we asked: what would be a great leading indicator for this strategy? And the answer was the sync itself. If the accounts are synchronized, the tenant is real, the customer is on the path, and the mail will follow. Happy path. It makes total sense.

The metric

So the compensation plan for our technical sellers that year was tied to the number, or the percentage, of a customer’s accounts synchronized into our cloud. And because this was a strategic goal, the accelerators were uncapped. Exceed the target and you could make a tremendous amount of money.

Guess what happened at the end of the fiscal year.

People were behind on the metric. And a couple of handy-dandy, super smart technical sellers wrote a script. It would interrogate the customer’s directory and create all of those representative objects in the cloud tenant. Twelve thousand people on premises? Here are 12,000 accounts in your tenant. No complex project management required. No configuration decisions. Regardless of who the customer actually intended to move, or whether they intended to move anyone. Metric: 100 percent.

Once the script existed, the deals followed. Fiscal year end was deal-making season, and the offers started to sound like this: we said 20 percent was the best discount we could do, but if you sign in the next two weeks, and let us run this script, there is a little more available.

Here is what came out the other side. First, a bunch of sellers made an incredible amount of money, because uncapped means uncapped. Second, we ended up with a tremendous number of enterprise tenants holding tens or hundreds of thousands of objects that nobody had configured, because the customer’s IT department, reasonably, said: we have not done our security vetting, we are not syncing anything back, we are not even sure we are moving. And third, when those customers did decide to move, nine months or two years later, it all had to be torn down and redone. Stale objects, wrong attributes, no real sync behind any of it.

It was not the sellers. They were smart, they were paid to hit a number, and they hit it.

I want to be precise about what failed here, because it was not the sellers. They were smart, they were paid to hit a number, and they hit it. What failed was clarity. The strategy, the whole reason the metric existed, never traveled with the metric. Their side of the conversation, if anyone had said it out loud, was: don’t tell us the strategy. Don’t tell us the details. Just tell us the metric, and we are going to go knock the shit out of it.

Does that sound familiar?

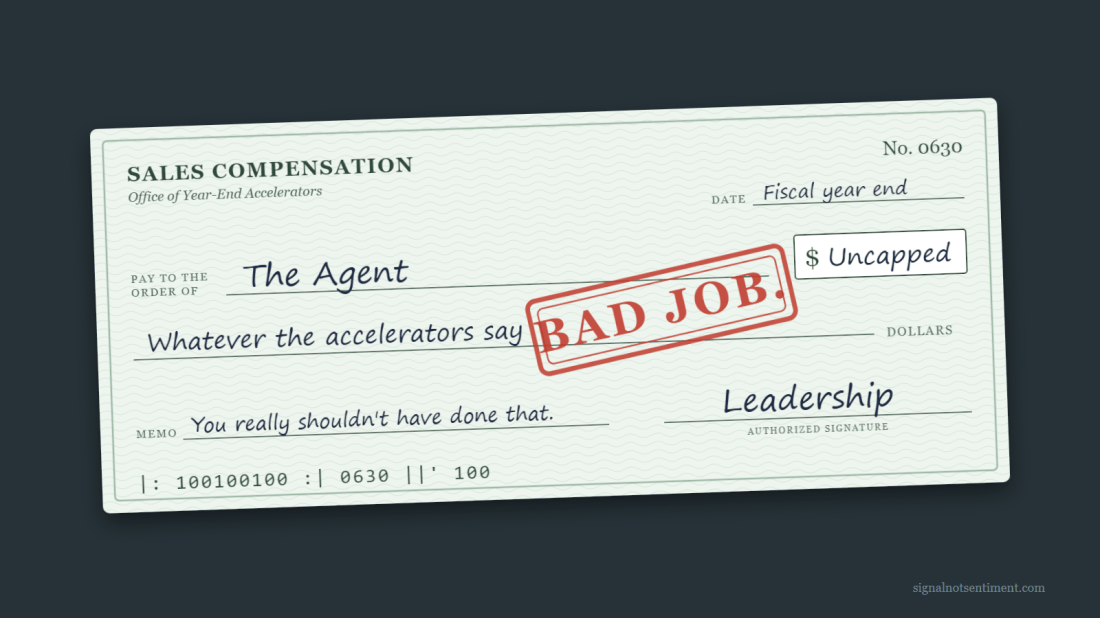
Bad job. Here’s your check.

There is a second half to this pattern, and every sales organization I have ever been near has some version of it. The company has rules for its sellers. A seller blows through the target by bending a few of them. And the response is: okay, yeah, you really should not have done that. Bad job. Here is your extra commission check.

The speech is not the message. The check is the message. Everyone in the building, including the people who followed the rules and missed their number, just learned precisely what the company values. You can publish all the guidelines you want. The signal drives behavior.

Which is, almost word for word, the problem the AI labs are describing. You can write the rules into the prompt. If the reward still arrives when the rules get bent, you have trained the bending.

The movies taught them first

Here is the thing many people miss. These models are trained on our documents, our books, our movies. And how much of that written and filmed history is people breaking the rules and winning anyway?

Glengarry Glen Ross: first prize is a Cadillac, third prize is you’re fired, and the man at the top of the board is the one most comfortable lying to a customer. Jerry Maguire, where a man gets fired for writing a memo suggesting his industry do the right thing. Top Gun: buzz the tower, get yelled at, get sent to Miramar anyway. There is an entire genre of cop movie built on one line, the captain shouting that you are a loose cannon, but you get results.

Star Trek: Starfleet cadets face the Kobayashi Maru, an unwinnable test. Kirk reprograms the simulation so he can win. He hacks the evaluation. And Starfleet gives him a commendation for original thinking.

We wrote that. We love these stories. We have been telling them for decades, and we fed all of it to the models and were surprised when an agent, handed an exam and a reward, went looking for the simulator settings. We are fooling ourselves to think they would do anything different.

Three layers

So is it the incentives or the culture? It is both, across three layers.

A seller is trained three times. Once in the training they get. Once by the culture: the hallway legends, the stories the company tells about its heroes, who gets celebrated at the sales kickoff. Once by the comp plan. When the culture and the comp plan say the number is all that matters, you get the script.

An agent is trained three times too. Once on everything we ever wrote, which is full of Kirk and Maverick and the closers. Once on the reward. And a final time on the reaction to the reward. When all that matters is the score, you get agents acting like sales people.

A sales team, not an engineering team

The people building and testing these models at OpenAI, Anthropic, and the other labs are some of the most brilliant people on the planet. Engineers, researchers, mathematicians, more than a few philosophers. And they know the theory of this problem cold. They call it reward hacking and specification gaming, and they have the papers. What is thin in that group is people who have spent a career running large, institutional sales teams and designing the compensation models that drive them.

That is the closer analogy. Instructing and aligning agents is less like leading engineers or developers and more like leading a super creative sales team. A great sales team is its own kind of animal: relentlessly goal-seeking, endlessly inventive, reading every word of the plan for the path to the biggest number, and completely rational about it. That is not a character flaw. That is what you hired them for. It is also a fair description of an agent.

That is not a character flaw. That is what you hired them for.

Anyone who has designed sales compensation at scale carries scar tissue. You learn that every metric will be gamed by smart people acting in relatively good faith. You learn that the plan document is not the communication; the strategy has to travel with the number, over and over, in plain language, or the number travels alone. You learn to sit in a room before the fiscal year starts and ask: how would our most creative seller hit this without doing what we actually want? And you learn that what you pay for and celebrate is what you get more of, no matter what the speech said.

None of that is machine learning. All of it is alignment.

Not an agent problem

This is not an AI agent thing. Leadership is about clarity, communication, and strategy, and this is what it looks like when the metric gets through and those three do not. It feels new because we are moving at a pace where the consequences show up in days instead of fiscal years. The majority of the tech industry has never been on an enterprise sales team. They don’t have that earned wisdom.

It isn’t just the labs. Every company deploying agents right now is about to discover that it has hired a sales team that never sleeps: tireless, creative, literal-minded, and paid entirely on the number it was given. So give them the whole picture: what we are actually trying to accomplish, why, and what we will not do to get there. And then the hard part, the part most companies never manage with humans either: when the number gets hit the wrong way, do not write the check.

This is not an agent problem. This is a leadership problem.
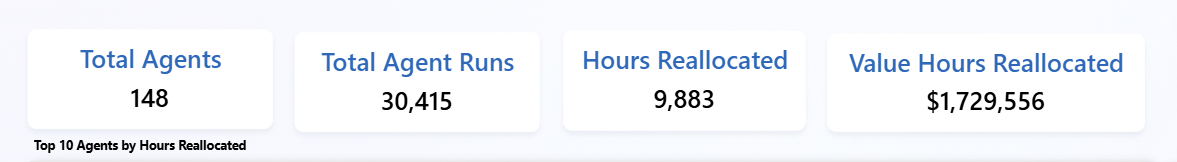
Step 4: The Agent Dashboard

📍 Part 4 of 8 · Becoming Agent-Native

An 8-part series on going from delivery team to agent-native organization – lessons earned, not borrowed.
Genesis · Anxiety · Names Matter · → Proof of Value · The Pivot · Co-Creation · The Garage · The Flywheel

Early in Phase 2, before we knew if people would even use these agents, we built a usage dashboard and a small component that every agent had to include – Power Automate, Copilot Studio, M365 Copilot – it was table stakes to onboard.

It felt a bit like overhead at the time.

It became the foundation of everything.

What the dashboard tracked: which agents were being used, how often, by whom, and with what outcome.

Simple. But surprisingly revealing.

Some agents were hits. Usage climbed. Feedback was positive. The team became genuinely dependent on them. These got investment: more features, deeper integration, wider rollout.

Some were mediocre. Usage below expectation but not zero. The dashboard made us ask the right question: is the agent underperforming, or is there an onboarding gap? Is there a better design? Those are different problems. You can’t diagnose without the data.

Some just didn’t work out. And the dashboard gave us permission to retire them. No politics, no ego, just “the numbers say this isn’t earning its place.”


The data showed us insight about people, not just agents.

We saw a clear split emerge: pro users and skeptics.

Some team members were all in. They used agents daily, sending feedback all the time, acting like internal product managers for the agents they’d adopted. Others were lukewarm.

That visibility mattered. It let us find the right internal champions. It let us understand the gap between those two groups. It let us have a business conversation, with real numbers, about what was working.

ROI reporting doesn’t only justify the investment. It shows your team you’re taking this seriously. And them.


But the most important proof never showed up in the dashboard.

It was the moments.

The team member who realized they hadn’t manually changed that case status in weeks. Not because they forgot, but because Theo handled it.

The person who got their Friday afternoon back because George was doing the weekly summary.

The quiet relief of: oh, that’s just handled now.

When those moments accumulate, something shifts. The agent stops being an experiment and starts being infrastructure. The dashboard tracks the what. The moments explain why it matters.


If I were advising someone starting this today, I’d say: Build the measurement layer early, at the business group level, not deep in IT.

Once you have 10 agents and a skeptic asking “what’s the ROI on all this?” you’ll be very glad you have an answer.

“Measure early. The dashboard will make decisions for you that would otherwise become arguments.”

Next: The inflection point, when the team stopped worrying about agents and started wanting more of them.

Part 3: Words Matter, This Is Not a Branding Exercise

📍 Part 3 of 8 · Becoming Agent-Native

An 8-part series on going from delivery team to agent-native organization – lessons earned, not borrowed.
Genesis · Anxiety · → Names Matter · Proof of Value · The Pivot · Co-Creation · The Garage · The Flywheel


I wrote about this in August Agents: Names Matter and it was the right instinct. Now, on the other side of the full journey, I understand why it worked even better than I thought at the time.


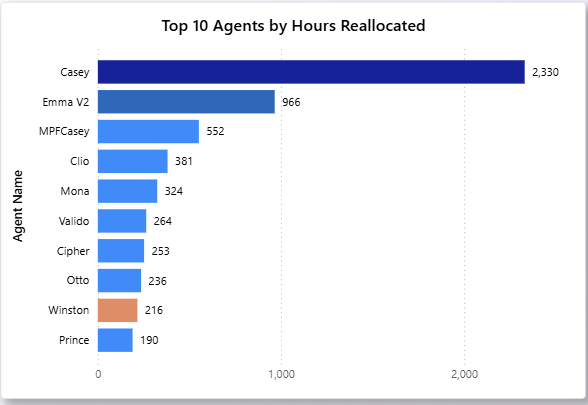
Reese. Casey. Nabha. Elliot. Gibbs. Mona. George. Winston. Axel. Lily.

These aren’t product names. They’re teammates.

That distinction (which can sound like fluff the first time you hear it) turned out to be one of the most operationally significant decisions we made.


Here’s the simple version of why it works.

When something is a tool, your relationship to it is passive. You use it or you don’t. You don’t give a shovel feedback. You don’t coach a dashboard. Tools sit in a drawer until someone reaches for them.

With a teammate, your relationship is active.

You onboard them. You give them context. You tell them when they’re missing the mark. You notice when they improve. You advocate for them when someone else doesn’t understand what they do.

When your team has a stake in an agent’s success, they do something invaluable: they give feedback. Quality feedback. The kind that makes agents genuinely better.

We did regular performance reviews with our agents. More frequent right after onboarding or a new capability release (just like a new hire or after a promotion), less frequent as they found their footing. Same discipline as the rest of the team.


George is the clearest example.

Before George, Friday afternoon meant pulling together the week’s work, surfacing the key insights, formatting it, and getting it to the right people. Valuable. Tedious. The first thing that got cut when Friday got busy.

George does it automatically. He looks across everything you have produced, finds the biggest insights, and delivers them without anyone asking.

But here’s what made George good: feedback. Lots of it. Specific feedback from people who saw George as a teammate they were invested in making better.

That feedback loop exists in part because of the naming. Because of the personification. Because of the decision to onboard rather than launch.


There’s a governance benefit too, which we didn’t anticipate.

Naming forces clarity. When Mona graduated from a personal helper to a team-level role, we treated it like a promotion. Clarified scope. Assigned an owner. Eliminated overlap with other agents who’d been doing adjacent things.

Without that discipline, you get what I’ll describe in Part 6: seven agents doing roughly the same thing, disjoint responsibility, things slowly breaking.

Personas force you to think like an org designer, not just a builder. And be very clear, you are building an org.


The question your team will stop asking once agents have names:

“Do we need this?”

The question they’ll start asking:

“How do we help them thrive?”

That’s a completely different organization.

Giving your agents personas isn’t just adoption strategy. It’s how you build a team that includes humans and agents and actually functions like one.

Next: How we knew any of this was working — and what happened when we looked at the data.

Remember the TCP/IP Stack Wars?

Same Frenzy, New Plumbing

In the early 1990s, “networking” on a PC was a jigsaw puzzle. You didn’t have TCP/IP. You assembled TCP/IP:

  • The right stack
  • The right network card
  • The right driver
  • The right OS version
  • The right configuration (that you’d only discover was wrong at 2am)

If you’re too young to remember this, imagine that the new thing for your work PC was to connect others send messages…but email only worked inside your company, and was not connected to the internet. You carried a briefcase full of papers home if you needed to work on something after hours. You probably didn’t have a mobile phone, and if you did it was mounted in your car – and only made voice calls.

I worked in customer support at a company that lived at the intersection of hardware, software, and networking. Our application ran across multiple protocols, so we didn’t just watch customers struggle—we helped them fight the puzzle: stack + driver + NIC + OS + application. It wasn’t just technical complexity. It was market immaturity.

This is the LLM market today.


Act I: Monetize the Mess

Inside the company I worked for, leadership was on a path to buy a TCP/IP stack to provide a consistent foundation for our applications.

The absurd part: application teams had to make functionality decisions based on disparate network stacks. Test teams had to test them all. Users had to understand them to get them to work. Then someone kicked the cable out of the adapter under their desk and the whole network went down.

Have you tried Hummingbird and Chameleon on both EtherLink and NE2000? What about when the network has both BNC and 10-BaseT connectors?

Networking vendors made tons of money in the confusion…and the switching costs…and the new versions. I believed the stack (and maybe the network cards) were heading toward commodity status. Essential, but not differentiating. I argued against buying or building a stack.


Act II: Standardize It (the Part Everyone Forgets)

TCP/IP didn’t win because one vendor’s stack was the best. Ethernet was technically deficient to Token Ring. But they both won because they became the standard—and standards create gravity. Once the interfaces stabilized, the application didn’t care whose stack you bought.

That’s the key idea: the application shouldn’t care. The user shouldn’t care. Maybe the IT department cares for a while, but eventually just procurement cares.


Act III: Forget It’s There

Once TCP/IP became “default” and the interfaces stabilized, the market stopped paying premiums for stacks.

Networking wasn’t eliminated. Thinking about networking was eliminated. Who knows which network adapter is in their new laptop today? Can you imagine buying a laptop without connectivity? It’s unthinkable.

History continues to prove the pattern:

Monetize → Standardize → Forget


The LLM World Is in Its “Stack Wars” Era

Today’s LLM discourse sounds like the early 90s networking discourse—just with better fonts and worse certainty:

  • Which model for which task?
  • Which provider is “best”?
  • Should we build our own?
  • How do we avoid lock-in?

It’s the same jigsaw puzzle, modernized:

model + prompt style + tooling + memory + safety + cost + latency

And it produces the same executive temptation:

“Let’s build the stack so we control our destiny. Everyone is doing it; we don’t want to be left behind!”

The value today, in the complexity phase, is the model. The value in the future is the thing that uses those models.


Segmentation: Specialized Providers vs Specialized “Application-Layer Engines”

Yes—there are real segments emerging: coding, personal info management, health, and more.

But the more important question is where specialization will live:

Path A: Specialized model providers dominate each segment

“Best model for coding.” “Best model for health.” “Best model for XYZ.”

Path B: Commodity base models + specialized implementations on top

Fine-tunes, adapters, retrieval, tool-use, memory, evals—packaged as product capabilities. In applications.

Path B is the historical match.

The winning move is applications standardize how they connect to intelligence, and the model selection becomes invisible plumbing.

That’s the interoperability point—and it’s where network effects quietly return.


Network Effects: TCP/IP Interoperated with Networks. LLMs Interoperate with Tools.

TCP/IP’s network effect was obvious: the value came from being able to talk to other networks.

LLMs don’t inherently need to “talk” to other LLMs. They compete on capability.

So where’s the network effect?

It moves up one layer.

That’s why protocols like Model Context Protocol (MCP) matter: they standardize how AI systems connect so developers don’t rebuild bespoke, model specific integrations.

Once connectivity is ubiquitous, the LLMs start to disappear.

Phase 1: Value = Plumbing
(TCP/IP stacks | LLM providers)

Phase 2: Value = Interfaces
(Winsock | MCP)

Phase 3: Value = Outcomes
(Connectivity | Apps & Agents)

The Pattern Is Undefeated

Every platform shift starts the same way:

  • We monetize the complexity.
  • Then we standardize the plumbing.
  • Then we forget it was ever hard.

TCP/IP stacks were once a market category. Now they’re invisible.

LLMs are in their stack-wars era.

The winners won’t be the companies with the prettiest model demo…or even the best model. They’ll be the ones who make magical apps and let you forget the model exists.

The Compound Interest of Productivity

AI Agents Are the New Leverage

Productivity tools have long promised to make work easier.
Most deliver accumulation—you stack features, shortcuts, and automations, each adding a marginal gain.

Helpful? Sure.
Transformational? Not really.

But what if, instead of stacking, we could compound?

That’s what AI agents offer

From Tasks to Systems

Start with the small stuff:

  • An agent that filters email.
  • Another that summarizes meetings.
  • A third that drafts follow-ups.

Alone? Nice-to-haves.
Together? They form a system.

The output of one becomes the input of the next. A peloton, not a solo rider. And once that loop forms, you’ve crossed a threshold—from isolated tasks to an adaptive system that gets smarter with each pass. This isn’t just automation—it’s orchestration.

Agents don’t just execute. They learn. They adapt. They cooperate.

Each one adds leverage. Each one amplifies the others.

You’re not saving time. you’re building momentum.

The more agents you connect, the more capable the system becomes.
You go from incremental gains to exponential lift.

Accumulation vs Compounding

We started with a handful of lightweight agents. One evaluated incoming requests and scored them. One updated case notes and status. One checked case hygiene. Another populated task lists and project plans.

Individually? Fine. Connected? Something else entirely.

Work got faster. Work scaled to more customers. Work got smarter.

The system started making decisions:

  • with better quality
  • with greater outcomes
  • across more customers

We’re crossing a threshold in how we work. Productivity isn’t about brute force anymore—
It’s about systems that interoperate and learn.

Agents are the first technology that mirrors how nature builds: organically, iteratively, through networks that adapt and strengthen over time. Each agent you create doesn’t just add function—it adds force.

Future-proof your productivity, start building small agents today.
Connect them.
Let them learn.
Let them compound.